Reflection on October 5 introduced Beam, its first announced model designed for coding, reasoning, and agentic tasks. Built as a sparse mixture-of-experts (MoE) architecture, Beam pairs 501 billion total parameters with 23 billion active parameters per token. The model is currently available only to select early users via a waitlist. Reflection plans to release its weights under Apache 2.0 later in October, alongside a technical report, model card, and developer artifacts.
The company frames Beam around efficient reasoning and code execution. Beam is text-only; the announcement shows it using text returned by tools, including an external optical character recognition (OCR) API. To control compute usage during inference, Reflection implemented an effort parameter that it says adjusts the balance between reasoning length and task performance.
Training Scale and Compute Math
According to Reflection, Beam was trained on 23.8 trillion pretraining tokens and underwent more than 100 million reinforcement learning rollouts. The reinforcement learning run utilized 10,500 Nvidia GB300 GPUs over a four-week span.
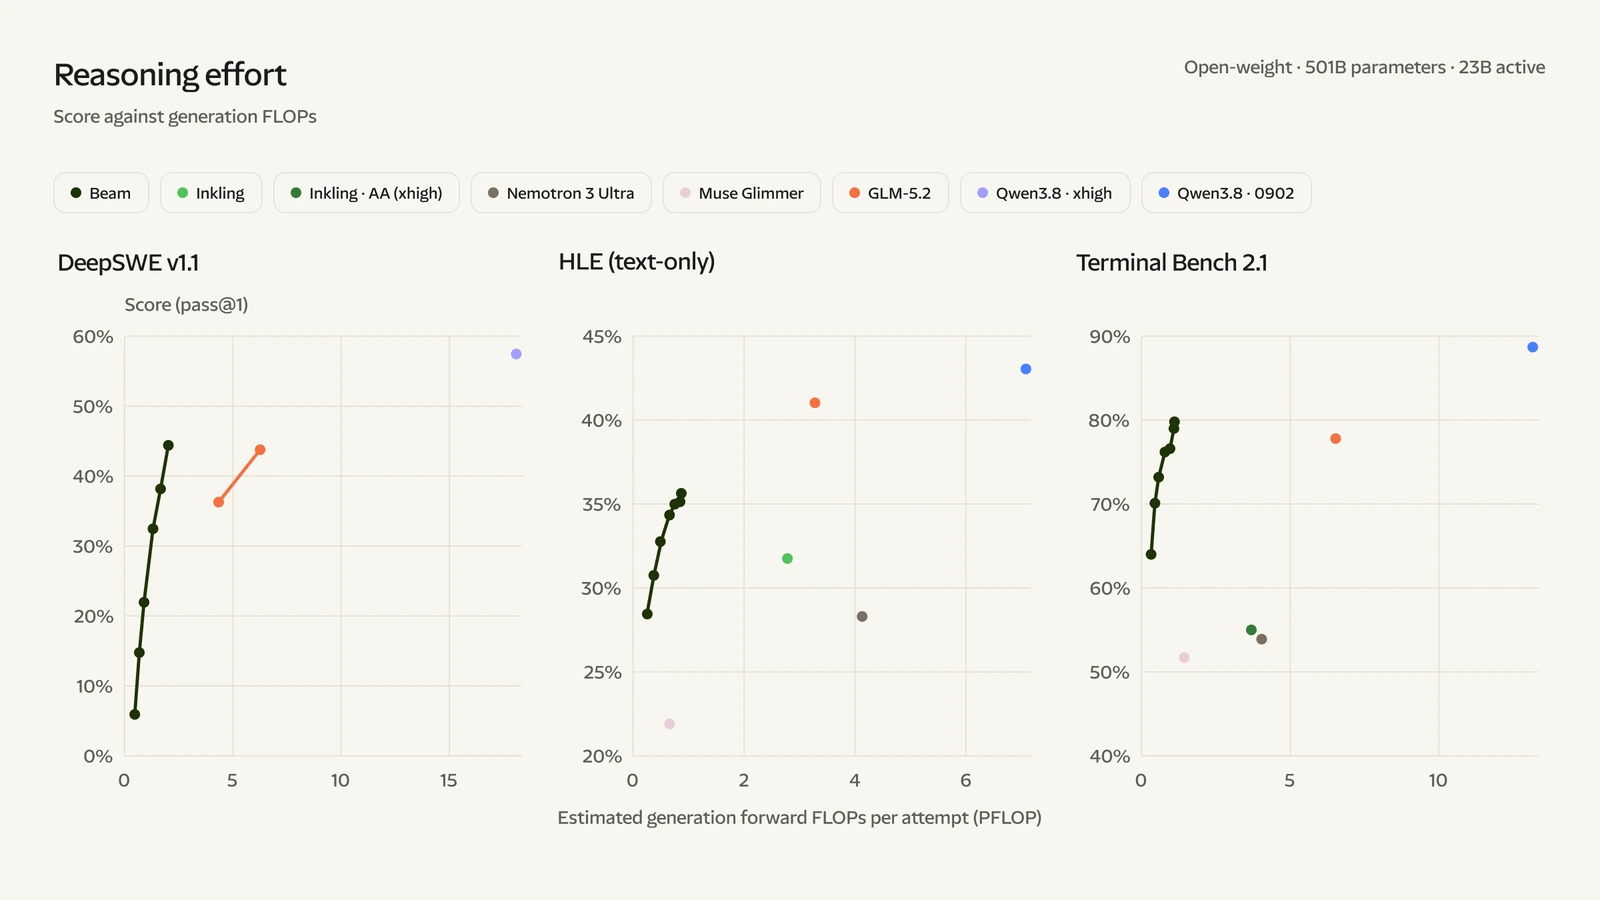
Reflection claims that Beam consumes 3x to 4x less inference compute than GLM 5.2 during advanced reasoning workloads. That comparison, however, uses an approximate generation-compute calculation:
- Calculation formula: The company estimates compute as
2 * active parameters * generated tokens, with generated tokens encompassing both internal reasoning and final output tokens. - Omitted factors: This approximation explicitly excludes prefill stages, context-dependent attention operations, and general serving overhead.
- Cost discrepancy: Reflection's estimate is not a measurement of latency, operational expenditure, or customer API bills.
Reported Benchmarks and Immediate Availability
On internal evaluations, Reflection reported that Beam scored 44.4 on DeepSWE v1.1 and 80.1 on TerminalBench 2.1. The company noted that larger models, such as Kimi K3, continue to outperform Beam in raw capability. These figures and the comparison with Kimi K3 come from Reflection’s evaluations.
Final red-teaming and safety evaluations remain underway. The announcement does not specify a general availability date, API token prices, or minimum local-hosting hardware. For now, access remains restricted to waitlist applicants ahead of the weights release planned for later in the month.