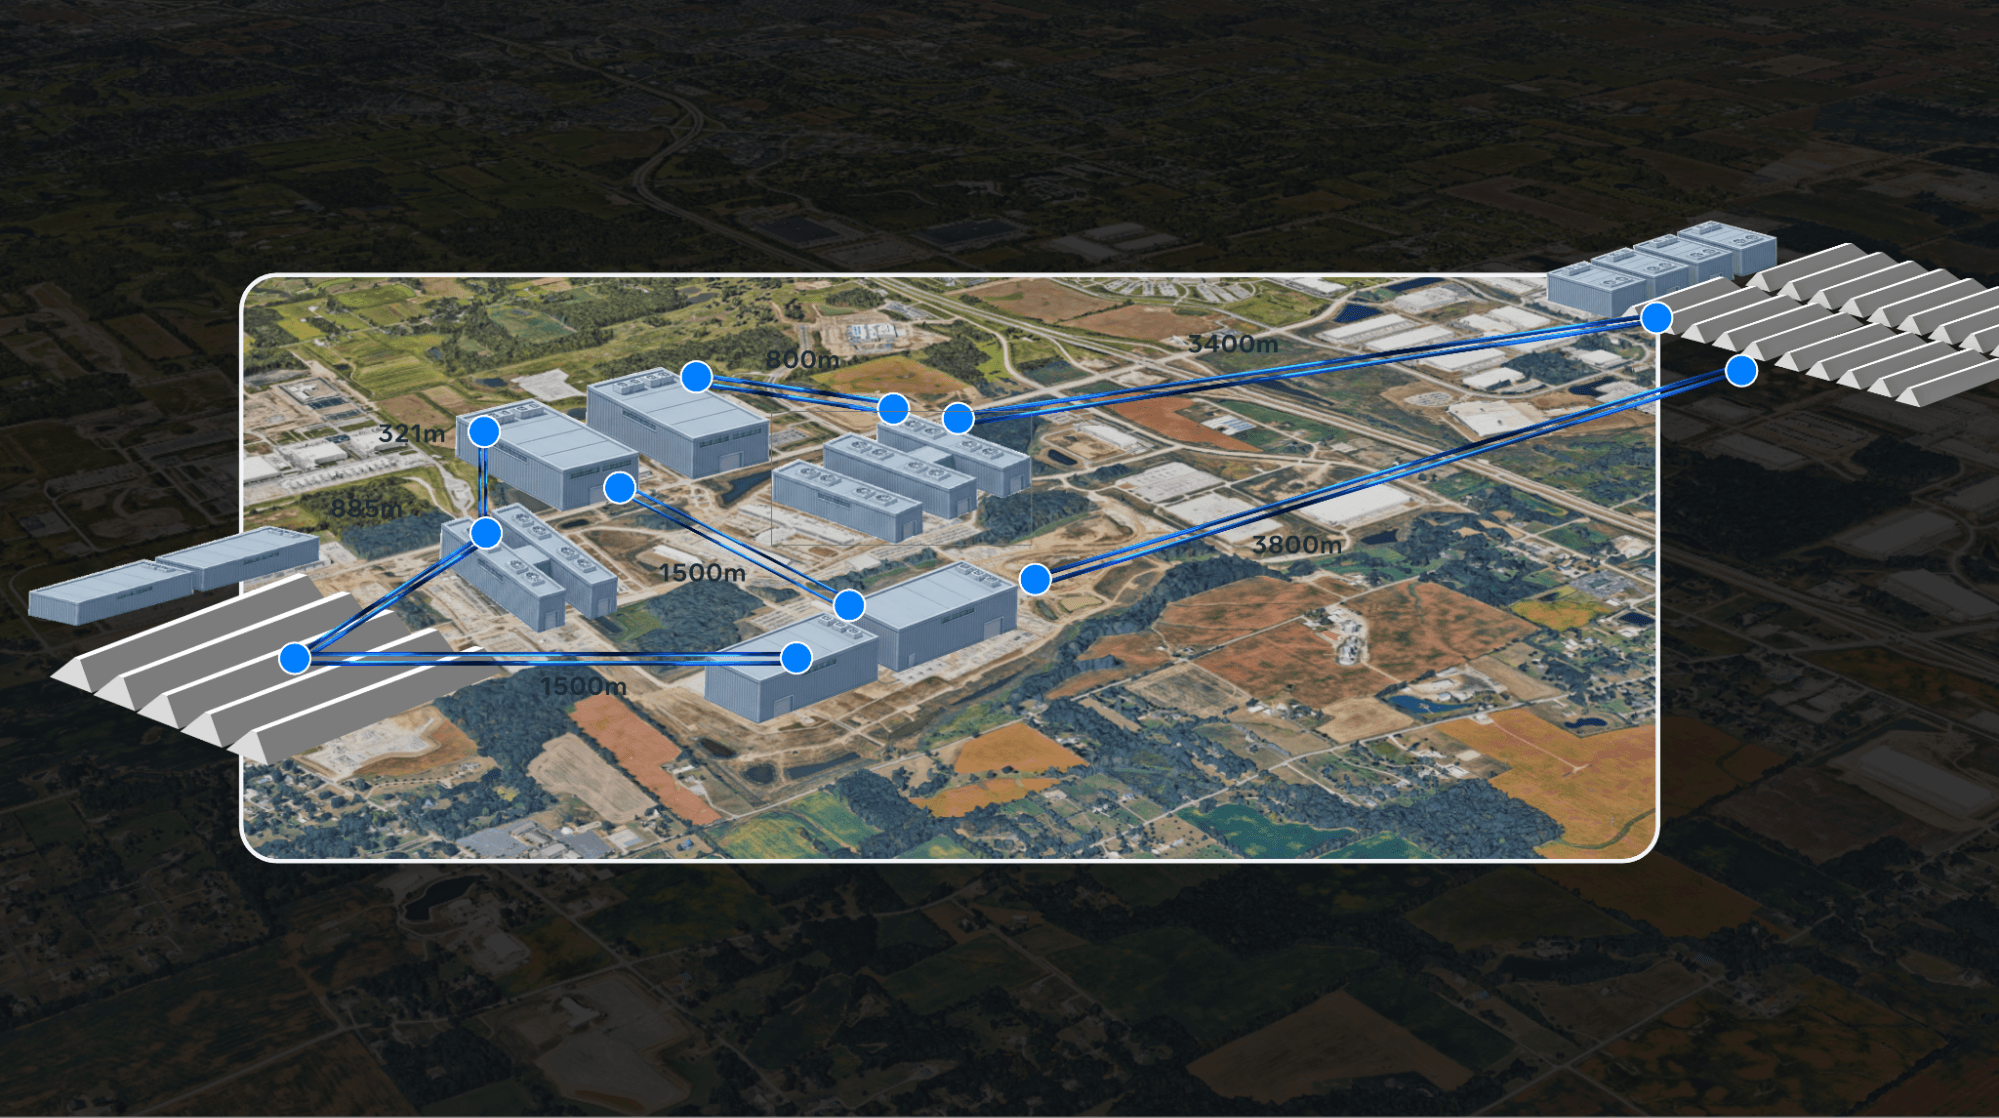
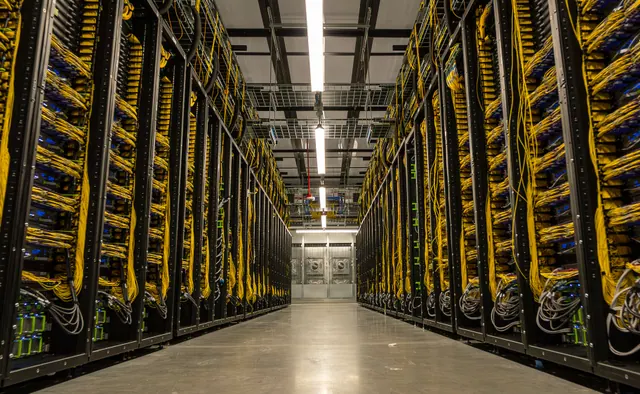
Meta said on October 19 that the first phase of Prometheus, its AI training supercluster in New Albany, Ohio, is complete and has already trained Muse models, including Muse Wonder. The company says the cluster currently connects hundreds of thousands of GPUs across multiple buildings; roughly one million GPUs is its eventual target.
That is a concrete operating milestone for a project Meta previously described as a gigawatt-scale buildout. In its September 2025 infrastructure overview, the company explained that Prometheus would combine conventional data center buildings, temporary structures and nearby leased facilities to assemble a larger training system.
Keeping a Distributed Cluster Working
The new engineering account describes dedicated Ethernet networks linking GPU systems within buildings and across sites. This matters because coordinated training can lose time when one component fails or communication stalls.
Meta reports that useful training work occupied more than 85% of Muse Wonder pre-training time and more than 90% of reinforcement-learning time. These are company-reported operating results, not independent measurements or public service guarantees.
Prometheus uses NVIDIA GB200 and GB300 systems today. Meta says Vera Rubin-based hardware will join later, while power controls, spare GPUs and liquid cooling help sustain the existing fleet. The announcement does not put a date on reaching the million-GPU target.