A very seductive number
In the lore of AI infrastructure, there is always an alluring metric that promises to make computational scarcity disappear. When DeepSeek published the training figures for V3, the figure was an astonishingly lean compute budget—a headline number that Nathan Lambert analyzed in his Interconnects critique, demonstrating that a seductive training-cost tally often conceals the massive capital, human engineering, and infrastructure ecosystem required to make such efficiency possible.
With DeepSeek’s release of V4.1 Flash in September 2026, the industry has encountered a new magic number: 890 bytes.
According to the model’s technical report, 890 bytes is the active global key-value (KV) cache footprint required per token during generation. For infrastructure engineers running long-horizon autonomous agents, that figure sounds like an escape hatch. Modern autonomous agents do not fail because their backbones lack raw reasoning depth; they fail economically because long conversations require the system to remember everything that came before.
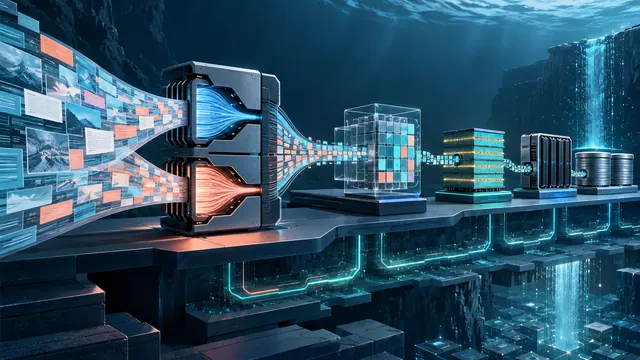
Every conversational exchange with an agent involves two distinct mechanical steps. First comes prefill, where the model ingests the system instructions, intermediate tool outputs, and historical context all at once. Second comes decode, where the model emits its response one token at a time. During prefill, the model computes key and value representations for every historical token—the KV cache. Think of this cache as an expansive physical desk: as a conversation lengthens, the assistant must keep every prior memo laid out flat so it can glance back at them while drafting the next sentence. If the desk fills up, the operator must either buy a larger, more expensive desk (high-bandwidth memory, or HBM) or shove old memos into a filing cabinet in the hallway (host RAM or NVMe storage) and retrieve them at great cost.
The promise of V4.1 Flash is that smaller memos leave more room on the desk. But I think the 890-byte figure is more revealing for what it relocates than what it solves: active context becomes lighter, while weight placement, host-memory staging and cluster operations remain stubbornly physical problems.
What the number actually measures
DeepSeek describes V4.1 Flash as a 552-billion-parameter backbone coupled with a 196-billion-parameter Engram component, pretrained on a multimodal corpus of 45 trillion tokens. Whatever the efficiency of its routing, this is not a small checkpoint.
Crucially, the architecture breaks the standard symmetry between prompt evaluation and generation. V4.1 Flash implements a Causal Encoder-Decoder structure that activates an estimated 8 billion parameters per token during the prefill phase, but expands to activate 16 billion parameters per token during decode.
The centerpiece of this memory reduction is Compressed Sparse Attention 2 (CSA2), which enforces aggressive cross-layer KV-cache reuse and compresses the stored cache down to FP4 precision.
The report gives two ratios that should not be blurred together. The global KV cache—the working memory used for active generation—drops to 890 bytes per token, roughly one-fourth of the V4 Flash footprint. The persistent cache—the state saved to a cheaper tier such as host memory or storage—drops to roughly one-eighth.
Conflating these two figures leads to severe provisioning mistakes. A one-eighth persistent cache footprint saves secondary storage budgets when shelving idle agent state, but it does not mean your active accelerator pool can suddenly pack eight times as many concurrent active decodes into expensive HBM.
The bottleneck has moved, not vanished
Why does this footprint matter? During decode, the system repeatedly reads the state of the conversation to produce the next token. As contexts and concurrent sessions grow, memory capacity and bandwidth can become as important as arithmetic throughput.
By compressing the active cache to 890 bytes per token, V4.1 Flash should leave more accelerator memory available for active sessions. The actual concurrency gain will depend on the runtime, batch shape, weight placement and latency target.
Yet, this mathematical gain runs directly into upstream physical reality. While the active parameters per token are modest (8B prefill, 16B decode), an operator hosting the open weights cannot allocate hardware for an 8B or 16B model. The entire parameter suite—552 billion backbone parameters plus the 196-billion-parameter Engram module—must reside across the collective memory pool of the serving cluster. Even with aggressive weight quantization, distributing these components demands extensive multi-accelerator partitioning.
DeepSeek's reference inference code provides an eight-way model-parallel example. The company explicitly presents it as a minimal correctness reference, not a certified minimum configuration or a production server. The honest conclusion is narrower than a hardware prescription: 8B or 16B active parameters cannot be read as the size of the deployment.
The economics of remembering
DeepSeek unified its API surface around the deepseek-flash endpoint, while setting legacy aliases to route into V4.1 Flash. It also said that from September 14, calls to deepseek-v4-pro would temporarily route to V4.1 Flash at the Flash rate until a V4.1 Pro release.
DeepSeek retains peak and off-peak pricing, with off-peak rates at half the peak rate. That may suit work that can wait, but it is a commercial policy rather than proof that the cache design will lower a particular customer's bill.
Smaller cache state can help at two moments: while a conversation is active in HBM, and while a dormant session is parked in a cheaper tier. It does not say how fast a runtime can evict and restore that state, how often an agent repeats context, or how much of the cluster is occupied by the checkpoint itself. Those are the measurements that turn an elegant byte count into an economic result.
Then the software gets in the way
Beyond cluster topology and token economics, integrating V4.1 Flash introduces acute downstream workflow friction.
The open weights are released under an MIT license, providing legal freedom for commercial customization and enterprise adoption. However, an open license does not equate to drop-in operational simplicity. Unlike many open-weight releases that provide standard Jinja template definitions compatible with general-purpose serving runtimes, V4.1 Flash explicitly omits a generic Jinja prompt template in its model card.
Instead, developers are directed to a dedicated Python encoder or DeepSeek's recipe toolkit. Tool-call tags have changed from V4; reasoning effort runs from 1 to 100, with reference points at 50, 75 and 100; the interface also supports interleaved images and mid-conversation system messages. None of these changes is individually alarming. Together they mean a migration is real engineering work, not an endpoint rename.
An elegant idea in an inelegant machine
DeepSeek V4.1 Flash is an elegant engineering intervention. It treats remembered context as a first-class systems cost rather than an incidental by-product of a large model.
Yet an elegant model design does not automatically create an elegant deployment. The cache claims have to survive a real serving stack that can place the large checkpoint, support the attention path and adapt the model-specific interface.
The number I would watch next is not another benchmark score. It is an independent production result showing throughput, latency and cost across realistic long-running sessions. Until then, 890 bytes is best read as a clue: DeepSeek may have made remembering much cheaper, while leaving the job of running the whole machine just as serious as before.