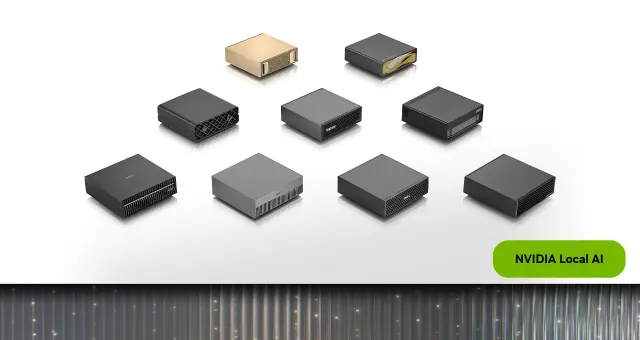
NVIDIA and system partners announced on October 2 a 64GB unified-memory configuration of the DGX Spark desktop AI platform, scheduled for commercial availability on Friday, October 23, 2026, starting at $4,999. The configuration will be sold exclusively through system partners, including Acer, ASUS, Dell, Gigabyte, HP, and MSI.
The new entry tier uses the same GB10 Grace Blackwell architecture, DGX OS environment, and underlying software stack as the existing 128GB version. NVIDIA positions the single-unit 64GB system for local agents, inference, fine-tuning, and data science workloads. According to NVIDIA, a single 64GB unit can handle models with up to 100 billion parameters, a stated capacity limit that should not be read as a promise that every model and context setting of that size will fit.
Clustering Specifications and Interconnects
For expanded memory capacity, two 64GB units can be linked over a direct 200GbE QSFP connection using integrated ConnectX-7 networking. NVIDIA states that linking two systems creates a 128GB combined memory pool capable of supporting models up to 200 billion parameters. Network configuration, device discovery, and setup verification are managed by an included tool named Sync Cluster Assistant.
In internal testing with the Qwen 3.8 27B model, NVIDIA reported up to a 1.7x performance improvement on a two-unit 64GB cluster compared to a single 64GB machine. That result describes NVIDIA’s test of this model; it is not a universal scaling factor or a comparison with a single 128GB system.
Hardware specifications from partner announcements outline compact form factors for the new configuration. Partner implementations, such as MSI's EdgeXpert 64GB model, feature 64GB of LPDDR5x memory housed in a 1.2-liter, 1.2-kilogram chassis. Networking interfaces include both standard 10Gb Ethernet and the 200Gb ConnectX-7 port for system interconnection, shipping with DGX OS preinstalled. MSI describes an intended operating model where teams use 128GB tiers for central development and distribute 64GB units to branch offices, retail locations, or factory sites.
Software Rollout and Near-Term Availability
NVIDIA also plans to release Sync Model Launcher at the end of October. It is intended to download and launch Qwen 3.8 27B on a single system or a cluster and configure OpenCode to use the model, making the local service accessible from a developer’s laptop.
A downloadable Blender installer is described as coming soon. NVIDIA also lists forthcoming 64GB playbooks for serving models with vLLM, running OpenClaw with a local model, and connecting multiple Spark systems for distributed workloads. These planned additions are separate from the DGX OS and AI software stack supplied with the hardware.