
The cloud platform is testing a way to keep AI agents from waiting on the computers that execute their commands. Better hardware still has to become a better service for customers.
01 · Tech News
Follow the AI industry.
179 reports following 64 companies and partnerships from model release to physical deployment.
All Tech News
Browse every report, including the current lead.
Tag: NVIDIA
16 articles · By source / event date · Page 1 of 1
MacBook Pro can cost less at 64GB, but RTX Spark has a credible AI performance lead in early matched tests. Personal buyers need to compare actual configurations, rather than platform slogans.
The new models target different deployment sizes: multimodal enterprise agents and local assistants, with a smaller 4GB edition scheduled for October 23.
Shared interfaces can give equipment makers a common target and buyers more options. The useful test is whether a specific replacement works in a supported system.
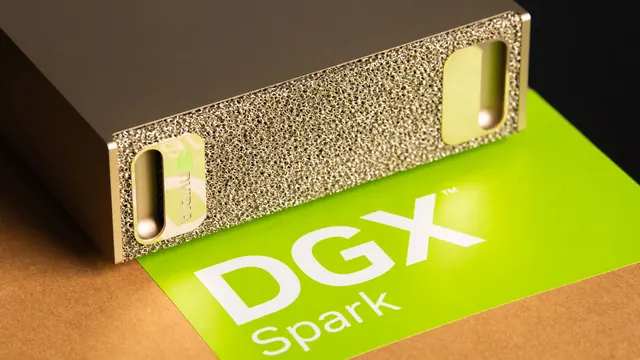
The new 64GB configuration starts $1,000 above the original 128GB model's launch price. Persistent memory shortages make that compromise understandable—and make a discretionary purchase harder to recommend.
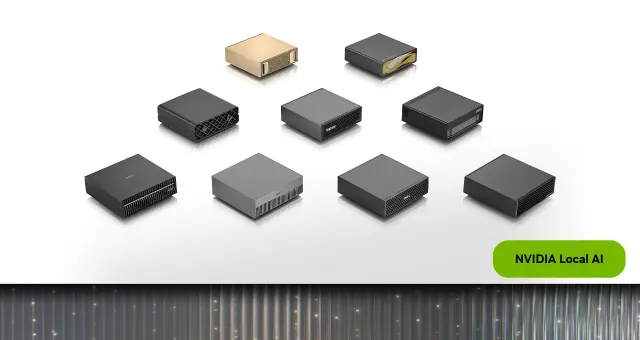
NVIDIA’s hardware partners will release a 64GB unified-memory tier of the Grace Blackwell-based DGX Spark on October 23, aimed at smaller local AI inference, agent workflows, and multi-unit clustering.
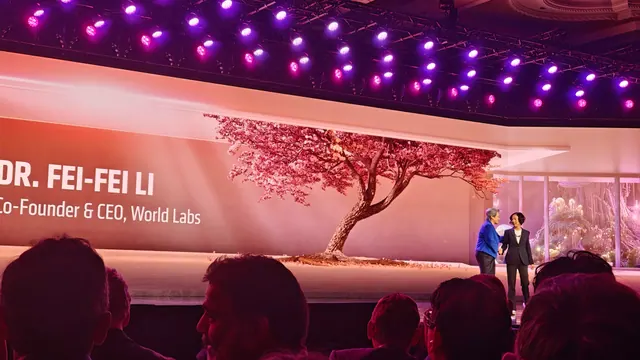
AMD wants a stronger position in the next phase of AI. Fei-Fei Li’s World Labs needs room to pursue expensive research while the market for world models takes shape. Their proposed deal brings those ambitions together.
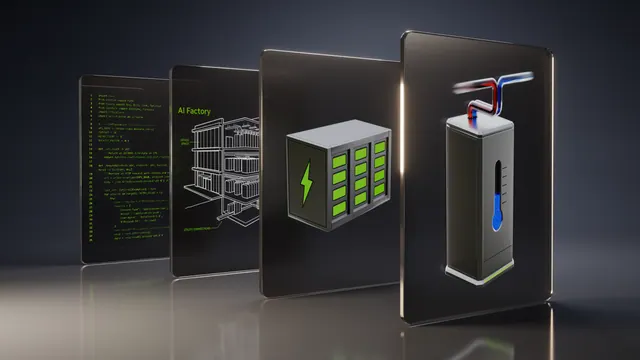
NVIDIA has launched a company-run qualification program for battery energy storage systems and cooling distribution units designed around its DSX AI-factory reference requirements. The program gives suppliers a defined NVIDIA review path, but it does not replace site-level engineering or establish site stability.
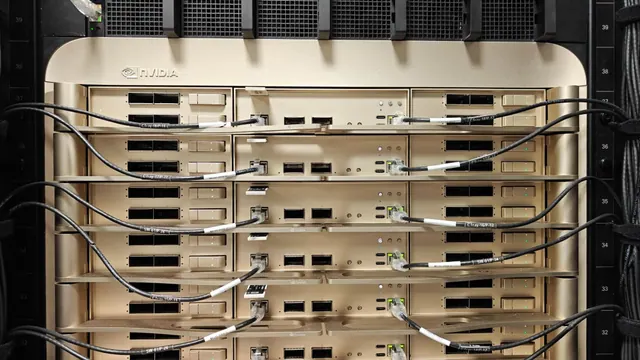
NVIDIA’s MLPerf Inference v6.1 preview numbers for the Vera Rubin NVL72 show impressive throughput gains on reasoning and multimodal workloads. But treating a tuned, rack-scale benchmark as a finished total-cost-of-ownership argument ignores the power, price, delivery, and utilization realities that enterprise infrastructure requires.
NVIDIA’s first Vera Rubin NVL72 MLPerf preview reports up to 3.7x the throughput of GB300 NVL72 on Qwen3-VL and up to 2.5x on DeepSeek-R1, under specific closed-division configurations.
NVIDIA's $12.9 billion agreement to acquire Hugging Face turns the open ecosystem's town square into an asset owned by the dominant chipmaker. Neutrality does not disappear on the day ownership changes, but it stops being an assumed reputation and becomes an engineering contract that developers must continuously measure.
The proposed deal would connect an AI accelerator supplier with a major open-model platform. Closing is expected in the first half of 2027, subject to customary conditions and regulatory approvals.
MediaTek will use NVIDIA’s NVLink Fusion platform to integrate customer-designed accelerators into rack-scale data centers, backed by a $3.5 billion convertible bond investment.
Amazon Web Services and NVIDIA plan to deploy two million additional GPUs across 2027 and 2028, expanding future hardware commitments alongside custom interconnects, federal clusters, and robotics integrations.
NVIDIA has started deploying its liquid-cooled Vera Rubin NVL72 racks across five infrastructure partners, within a broader platform spanning seven chips and five rack tray types.
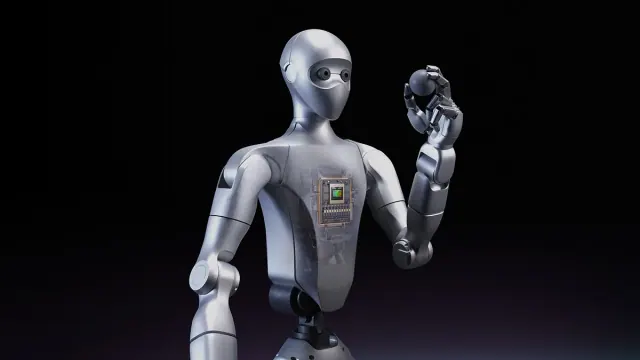
NVIDIA is pairing third-party robotics hardware with its Jetson Thor onboard compute and Isaac GR00T open software to standardize humanoid robotics research. Full reference robots are scheduled to ship through Unitree in late 2026, while software workflows for existing Unitree G1 humanoids are slated for an earlier release.