
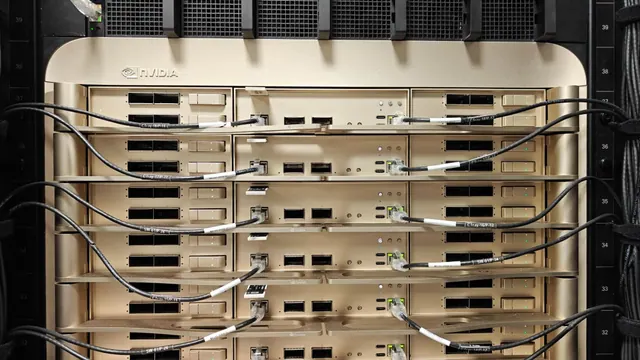
NVIDIA’s MLPerf Inference v6.1 preview numbers for the Vera Rubin NVL72 show impressive throughput gains on reasoning and multimodal workloads. But treating a tuned, rack-scale benchmark as a finished total-cost-of-ownership argument ignores the power, price, delivery, and utilization realities that enterprise infrastructure requires.
01 · Tech News
Follow the AI industry.
184 reports following 64 companies and partnerships from model release to physical deployment.
All Tech News
Browse every report, including the current lead.
Tag: MLPerf
2 articles · By source / event date · Page 1 of 1
NVIDIA’s first Vera Rubin NVL72 MLPerf preview reports up to 3.7x the throughput of GB300 NVL72 on Qwen3-VL and up to 2.5x on DeepSeek-R1, under specific closed-division configurations.